
Machine learning has made real inroads in cancer detection, diagnosis, and treatment, but cancer is a formidably complex disease, and that complexity pushes traditional models to their limits. Cancer involves a huge number of interacting biological variables: genetic mutations, protein expressions, patient history, imaging data, and more. Traditional models struggle to make sense of all this data at once. The more variables you include, the worse the models tend to perform: a well-documented phenomenon called the “curse of dimensionality”. And with cancer, there’s no shortage of variables to include.
Quantum computing offers a promising approach to tackle this complexity. By leveraging quantum mechanical phenomena, quantum computers can theoretically handle computational problems that would be exponentially costly for classical (traditional) approaches. At Cascade Quantum, we’re building Red Cedar: a framework designed for users at any level of quantum expertise to put quantum machine learning to work. With it, users can build quantum circuits, encode data, train models, and tune parameters to hit target performance benchmarks. In this post, we share our investigation into quantum advantage for oncological classification tasks across multiple data types and preprocessing strategies, including a methodology for fairly benchmarking quantum models against AutoML-optimized classical neural networks.
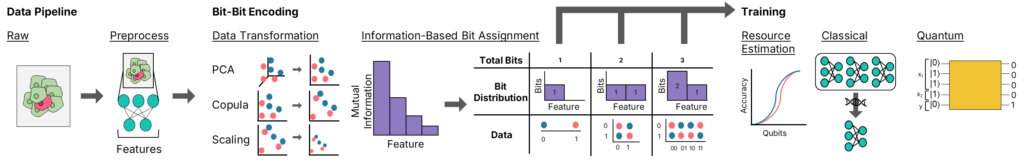
“Quantum advantage” is the term researchers use when a quantum algorithm outperforms the best available classical algorithm on the same problem. There’s been theoretical work suggesting quantum machine learning should have an edge on exactly the kinds of high-dimensional, complex data that show up in oncology. The question is whether that advantage holds up in practice. To find out, we tested the Red Cedar framework and classical machine learning models across three types of oncological data: tabular data (the well-known Wisconsin Diagnostic Breast Cancer dataset), omics data (genomic expression profiles from The Cancer Genome Atlas), and spatial data (medical images from the MedMNIST benchmark collection). For each dataset, we also tested different preprocessing strategies, which are techniques applied to the data before model training to reduce noise and improve performance.
One of the persistent problems in quantum machine learning research is that it’s difficult to know whether comparisons between quantum and classical models measure the actual potential of the models or just the effort put into optimizing them. We addressed this by using AutoML, software that automatically searches for the best neural network architecture and settings for a given dataset, so the classical models were as well-optimized as possible. We also used Cascade Quantum’s quantum machine learning resource estimation tool that estimates how many qubits would be needed to solve a given classification problem perfectly. This gave us a point of comparison beyond just the trained models: an upper bound on what’s achievable, and a way to gauge whether a dataset even has the complexity that might lead to quantum advantage.
On the datasets we tested, we found no evidence of quantum advantage. Across all data types and all preprocessing methods, quantum and classical models performed statistically indistinguishably from each other. Our resource estimation tool helps explain why. For quantum advantage to be plausible, a dataset needs to require more than roughly 50 qubits to encode; that’s approximately where classical simulation of quantum systems becomes intractable. None of the datasets we tested crossed that threshold. The Wisconsin breast cancer dataset, the most commonly used benchmark in quantum oncology research, required only around 15 qubits. The genomic datasets were similar. Even the medical imaging datasets, which came closest, didn’t clearly surpass the threshold when properly preprocessed. The datasets we used are the ones most commonly used in the research to attempt to demonstrate quantum advantage in oncology. Our findings suggest they simply aren’t complex enough to surface it.
Our results point toward a clear direction for the field: to demonstrate meaningful quantum advantage in oncology, researchers need to move beyond current benchmark datasets toward richer, higher-dimensional data. Multi-omics datasets, which combine genomic, transcriptomic, proteomic, and other data types, are a natural next step, as are multi-modal datasets that integrate imaging with molecular profiles. These are the kinds of data where the curse of dimensionality truly bites, and where quantum approaches may have the most to offer.
The practical obstacle is access. Oncological data is sensitive and heavily protected, and the datasets that are publicly available tend to be small and relatively simple. Closing the gap between quantum machine learning research and clinical reality will likely require deeper collaboration with healthcare and biotech organizations that hold large, complex, real-world datasets. In the meantime, we believe the benchmarking methodology we’ve developed here, combining trained quantum and AutoML-optimized classical models with resource estimation, provides a more rigorous foundation for this kind of research than what has typically been used. Rather than claiming quantum advantage on undersized benchmarks, the field can use tools like these to identify which problems are genuinely promising candidates, and focus effort accordingly.
To explore these ideas further, you can try the QRE web tool by uploading your own dataset and obtaining an estimate of the quantum resources required. Experimenting with different preprocessing choices can provide additional insight into how dataset structure influences representation. QRE serves as a first step in understanding whether quantum machine learning may be relevant for your problem. For a detailed discussion of our methodology, results, and implications, refer to the full paper1.
For more complex datasets that require deeper analysis or custom preprocessing, or to get early access to the full Red Cedar quantum AI framework, get in touch with Cascade Quantum, Inc. We would love to hear about your experience and the types of datasets you explore. You can reach out to us through our contact form.
References
- Sydney Leither, Thomas Lubinski, Michael Kubal, Sonika Johri, “Benchmarking Quantum and Classical Machine Learning Models on Oncological Data” 2026. Available: https://arxiv.org/abs/2609.03220 ↩︎